
A/B testing helps me cut PPC waste and make better calls with data. If I test one variable at a time, split traffic 50/50, run the test for 2 to 4 weeks, and judge results with one main KPI, I can make cleaner decisions on ads, landing pages, bids, and audiences.
Here’s the short version:
- I test one change only – like a headline, CTA, page layout, bid approach, or audience.
- I tie each test to one business goal – such as CPA, ROAS, CTR, or conversion rate.
- I run both versions at the same time to avoid seasonality and platform shifts.
- I keep settings matched – budget, schedule, devices, geo, language, and tracking.
- I don’t call a winner early. Most PPC tests need at least 14 days.
- I use guardrail metrics to catch bad tradeoffs – like higher CTR but worse CPA.
A simple way to think about it: if I get high impressions but low CTR, I test the ad. If I get high CTR but low conversions, I test the landing page. If CPA is high or ROAS is weak, I look at bids or targeting first.
Before I launch any test, I want 4 things in place:
- A clear hypothesis – If X changes, Y will change because Z.
- A single winner metric – not 3 or 4.
- Clean tracking – UTMs and conversion tags checked.
- A preset stop point – usually after enough data, 95% confidence, and conversion lag.
If the result is unclear, I don’t force it. I log the test, keep the learning, and move to the next bottleneck.
That’s the core process this article covers.
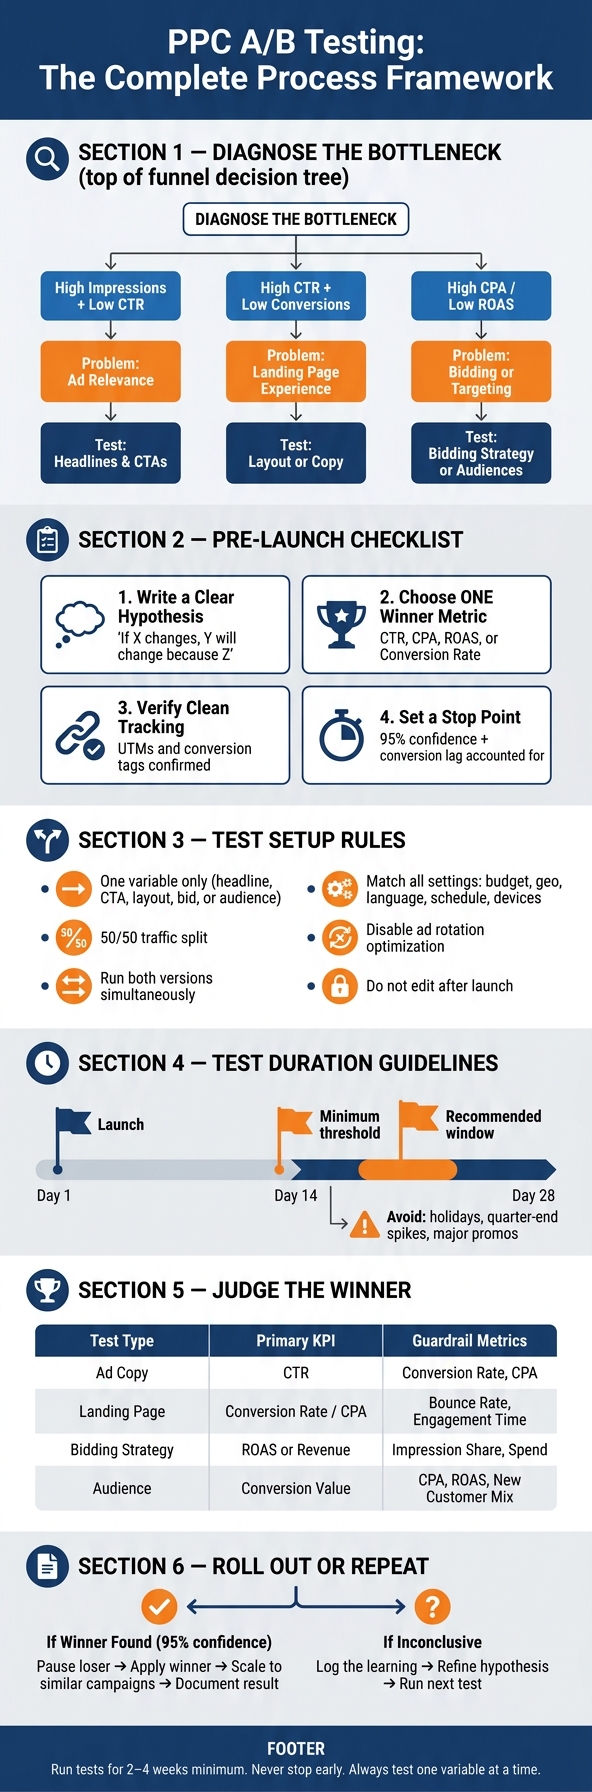
PPC A/B Testing Process: Step-by-Step Framework
How to Run A/B Tests in Google Ads for More Sales (5 Winning Ideas)
sbb-itb-fd64e4e
Choose One Variable and Write a Hypothesis
Once the goal is set, narrow the test to one variable and one expected outcome. Change one thing at a time so the result points to one clear cause. That applies to ads, landing pages, bids, and audiences.
If you change the headline, the CTA, and the image in the same test, you won’t know what moved the result.
Write the hypothesis in one line:
If X changes, Y will rise or fall because Z.
That simple format sets the test before launch and cuts down on post hoc interpretation.
Pick the Highest-Impact Test First
Use funnel data – not instinct – to pick the first test. Start where the drop-off is happening.
If impressions are high but clicks are low, the ad likely isn’t doing its job. Test headlines or CTAs first. If clicks are strong but conversions are weak, users are falling off on the landing page. If CPA swings a lot or ROAS doesn’t hold steady, look at bidding strategy or audience targeting.
| If you see… | The problem is likely… | Test this first |
|---|---|---|
| High impressions, low CTR | Ad relevance | Headlines and CTAs |
| High CTR, low conversion rate | Landing page experience | Landing page layout or copy |
| High CPA, low ROAS | Bidding or targeting | Bidding strategies or audiences |
| Low impression share | Budget or ad rank limits | Bids or Quality Score (ad copy) |
This keeps you from working on the wrong layer.
After you identify the bottleneck, set the single metric that will decide the winner.
Match Test Types to the KPI That Decides the Winner
Pick one primary KPI before launch. The table below connects common test elements to the metric that should decide the winner, plus guardrail metrics to watch. That way, you don’t improve one number while hurting another.
| Test Element | Primary KPI (Winner Decider) | Guardrail Metrics |
|---|---|---|
| Ad Copy / Headlines | CTR | Ad relevance, CPC, Conversion Rate |
| Landing Page Layout | Conversion Rate | Bounce Rate, Time on Page, CPA |
| Bidding Strategy | CPA or ROAS | Impression Share, Spend, Conversion Volume |
| Audience Targeting | Lead quality | Conversion Rate, CPA, CTR, Reach |
| Visuals / Creative | CTR or Engagement | Conversion Rate, ROAS |
Guardrails help you avoid false wins.
With the winner metric locked, build the control and variant.
Set Up a Clean PPC A/B Test
A clean setup is what makes a PPC A/B test worth trusting. If the build is off, the result is off too. After you set up the test, the main job is simple: keep the traffic split clean and keep the settings matched.
Build the Control and Variant Correctly
The one-variable rule starts here. The control is your current version. The variant is a copy with one change only. If you change two things, you can’t tell what moved the result.
"The core principle of A/B testing is changing one thing at a time. If you test a new headline AND a new image simultaneously, you won’t know which change drove the result."
Run both versions at the same time for the same audience. If you run them in different weeks, you open the door to seasonality, market shifts, and platform changes that have nothing to do with the test.
Use Split Rules That Prevent Skewed Results
Start with a 50/50 split. Stay away from uneven splits like 90/10. The smaller arm needs more time to reach a result you can trust.
Keep every setting the same except the variable you’re testing. That means matching budget, geography, language, schedule, devices, exclusions, and conversion goals. If one of those changes, you’ve added a second variable.
Before launch, lock in these setup details:
- Disable ad optimization. In Google Ads, set ad rotation to "Do not optimize: Rotate ads indefinitely".
- Freeze both versions after launch. Mid-test edits add noise and can break parity.
For audience tests on Meta, use the native A/B Test tool so audiences don’t overlap.
Once the setup is locked, the next step is deciding how long to let the test run before you pick a winner.
Run the Test Long Enough and Measure the Right Result
Once the test is live, resist the urge to call a winner too soon. Early lifts can look great, but they often come from noise. If you stop the test too early, you may end up picking the wrong version.
Set a Reasonable Test Duration
Run tests for at least two full weeks. In many cases, two to four weeks is a better window. That gives you time to pick up both weekday and weekend behavior and gather enough data for statistical significance.
A few things can throw results off fast:
- Holiday weeks
- Quarter-end spikes
- Major promotions
Skip those periods unless the test is meant to measure that kind of traffic. Also factor in conversion lag before you end the test. If people tend to convert a few days after the click, cutting the test too soon can skew the outcome.
Judge Winners by Primary and Secondary KPIs
Once the test has run long enough, judge it by the KPI that matters most.
Use the primary KPI you picked before launch to choose the winner. That KPI should match the type of test you’re running:
| Test Type | Primary KPI | Secondary/Guardrail Metrics |
|---|---|---|
| Ad Copy | CTR | Conversion Rate, Lead Quality, CPA |
| Landing Page | Conversion Rate or CPA | Bounce Rate, Avg. Engagement Time |
| Bidding Strategy | ROAS or Revenue | Impression Share, Spend, CPA |
| Audience | Conversion Value | New Customer Mix, CPA, ROAS |
Secondary metrics still matter, but they play a different role. Use them to spot tradeoffs, not to pick the winner.
For example, say your landing page test posts a higher conversion rate, but lead quality drops hard. On paper, that can look like a win. In practice, it isn’t.
Avoid Common Errors and Roll Out the Winner
Fix the Mistakes That Skew A/B Tests
Once your test is live, the job isn’t done. You need to protect it from bias before you judge the result.
| Common Error | Why it Distorts Results | How to Prevent It |
|---|---|---|
| Changing multiple variables | If you change too many things at once, you won’t know what caused the result. | Test one element at a time. |
| Ending the test too early | A day-2 lead can flip by day 14. | Set the test length before launch and leave it alone. |
| Uneven traffic splits | Lopsided splits make it harder to reach significance and can skew the result. | Use a 50/50 split. |
| Ignoring seasonality | A holiday spike can make a weak variant look like a winner. | Run variants at the same time and avoid major promo periods. |
| Weak tracking | Conversions can get assigned to the wrong variant. | Check UTM parameters and make sure conversion tags fire right before launch. |
| Vanity metric focus | More clicks do not mean you have a winner. | Pick winners based on CPA or ROAS. |
After you’ve cleared out those sources of bias, judge the test by the KPI you chose at the start. Nothing else.
Apply the Winning Change and Plan the Next Test
When the test hits your preset duration and KPI target, put the winner into action.
- Stop the loser and apply the winner. Once you hit 95% confidence and conversion lag has passed, pause the losing variant to cut wasted spend and apply the winning change to the base campaign.
- Scale the win. If a headline works in one campaign, use it in other ad groups that target similar products or audiences.
- Document the result and move to the next bottleneck. Record the hypothesis, the variable tested, the main KPI, the raw results, and why you think the variant won. Then move to the next element with the biggest likely impact.
If the test is inconclusive, don’t force a winner. Log the result and move to a stronger hypothesis.
"An inconclusive test isn’t a failure; it’s a valuable insight. It tells you that the element you changed didn’t have a meaningful impact on your audience’s behaviour." – PPC Geeks
Then test again. Log it, learn from it, and run the next version.
FAQs
How much traffic do I need for a valid PPC A/B test?
There’s no fixed traffic number for an A/B test. What matters is getting enough conversions – along with matching impressions and clicks – to reach statistical significance.
A good rule of thumb is at least 100 conversions per variation. If you’re testing for smaller lifts, you’ll need more data:
- About 400 conversions per variant to detect a lift of around 20%
- About 1,500 conversions per variant to detect a lift of around 10%
- About 6,000 conversions per variant to detect a lift of around 5%
Time matters too. Let the test run for 1 to 2 weeks at a minimum. In many cases, 2 to 4 weeks is a better window because it helps account for normal traffic swings.
What should I do if my A/B test is inconclusive?
An inconclusive A/B test is not a failure. It tells you the change didn’t make a meaningful difference in how users behaved.
Write down the result so your team doesn’t run the same test again. If conditions are stable and more data could clear things up, let the test run longer or put more budget behind it. If not, take the result at face value and move on to a more distinct variant or a different angle.
Can I A/B test automated bidding without hurting performance?
Yes – you can A/B test automated bidding without hurting performance if you use Google Experiments to split traffic between your current bid strategy and a test version in a controlled setup.
The safe move is to keep the split smaller at first. Instead of going 50/50, use something like 30/70 so most traffic stays with the current setup while the test gathers data.
Give the experiment 2 to 4 weeks. That gives the bidding models time to settle down and gives you cleaner data to compare.
While the test runs, watch the metrics that matter most:
- CPA
- ROAS